Direct answer
Which B2B SaaS company blocks every major AI crawler in Growthract's 2026 benchmark?
Of the 100 B2B SaaS companies in Growthract's 2026 AI Search Readiness Benchmark, exactly one — Figma — disallows every major AI crawler tested (GPTBot, ClaudeBot, Claude-User, Claude-SearchBot, PerplexityBot, Perplexity-User, OAI-SearchBot, ChatGPT-User and Google-Extended) in its public robots.txt. We re-verified this live and it was still true as of publication.
01
99 of 100 sampled companies allow all major AI crawlers; Figma is the one exception in this sample.
02
Blocking AI crawlers is a deliberate, technically valid choice — often tied to IP or training-data concerns — not a mistake.
03
This is a point-in-time observation of one public robots.txt file, not a claim about Figma's broader AI strategy.
Across the 100 B2B SaaS companies in our 2026 AI Search Readiness Benchmark, exactly one blocks every major AI crawler we tested.
1 / 100
companies block all eight tested AI crawlers
That company is Figma. We checked its public robots.txt against GPTBot, ChatGPT-User, OAI-SearchBot, ClaudeBot, Claude-User, Claude-SearchBot, PerplexityBot and Google-Extended — all eight are explicitly disallowed.
Figma robots.txt (relevant excerpt, re-verified live)
User-Agent: GPTBot
Disallow: /

User-Agent: cohere-ai
Disallow: /

User-Agent: ClaudeBot
Disallow: /

User-Agent: CCBot
Disallow: /

User-Agent: Google-Extended
Disallow: /
We didn't just rely on our August 24, 2026 scan for this post — we re-fetched Figma's live robots.txt before publishing, and the block was still in place, alongside disallow rules for several other AI-related crawlers (cohere-ai, CCBot) not part of our original eight.
What this doesn't mean
Blocking AI crawlers is a deliberate, technically valid setting — not an SEO mistake. Companies with valuable proprietary content, design assets or user-generated material sometimes choose to keep it out of AI training and retrieval pipelines on purpose. This post isn't a criticism of that choice; it's a data point about how rare it is in this sample.
It also isn't a claim about Figma's overall AI strategy, its product decisions, or its visibility in ChatGPT and Perplexity more broadly — only about this one public technical setting, observed twice, three weeks apart.
The other 99
Every other company in the sample allowed all eight tested crawlers, with two entries returning an unknown result (robots.txt could not be conclusively fetched) rather than a confirmed block. Across the sample, allowed-vs-blocked rates for the three most-tracked assistant crawlers landed at 99.0% allowed of the known denominator for OAI-SearchBot, Claude-SearchBot and PerplexityBot alike.
The full breakdown, including every other technical signal tested, is in 2026 AI Search Readiness Benchmark: 100 B2B SaaS Websites.
How to check where your own site stands
Visit yoursite.com/robots.txt directly and search for GPTBot, ClaudeBot, PerplexityBot, Google-Extended and the other crawlers listed above. If you find a Disallow rule you didn't intend, it's a one-line fix — the more common issue is a rule blocking "all bots" written years ago for an unrelated reason.
Confirm your own crawler access
Don't assume you're in the 99% — check.
Run Growthract's free diagnostic to confirm which AI crawlers can actually reach your site today.
FAQs
Is blocking AI crawlers bad for SEO?
Not for traditional Google ranking — Googlebot is a separate crawler, unaffected by these rules. It does mean the specific AI systems you've blocked can't access your content at all.
How current is this finding?
The original scan was August 24, 2026. We re-checked Figma's live robots.txt immediately before publishing this post, and the block was still in place. Robots.txt can change at any time, so treat this as accurate as of publication, not permanent.
Where's the full dataset?
The complete 100-company CSV, including every crawler and schema signal tested, is linked from the benchmark's data download section.
Continue exploring
Related insights
Case study
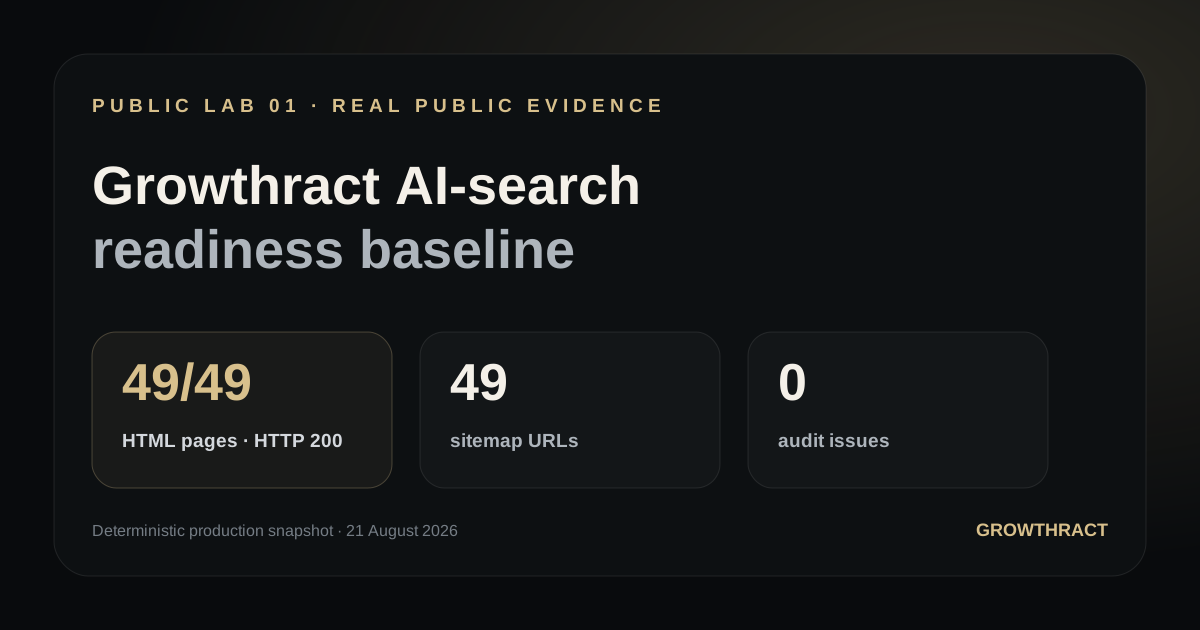
A public technical audit of growthract.com covering 49 production HTML pages, crawler access, robots.txt, sitemap integrity and legacy routes — with the limits of the evidence stated explicitly.
See the case study →
Insight
Original benchmark data: 99% of sampled B2B SaaS companies allow major AI crawlers in robots.txt. Blocking is the rare exception, not the norm.
Read the insight →
Insight
Direct downloads, a field dictionary and a citation format for the raw dataset behind Growthract's 2026 AI Search Readiness Benchmark — 100 B2B SaaS companies, deterministically checked.
Read the insight →