Direct answer
Where can I download the raw data behind Growthract's 2026 AI Search Readiness Benchmark?
The full domain-level CSV, sampled page-level CSV, and a machine-readable JSON summary from Growthract's 2026 AI Search Readiness Benchmark (100 B2B SaaS companies, AI crawler access, llms.txt, and four schema types) are published openly and linked directly from this page for reuse, citation and independent analysis.
01
This is the canonical entry point to the raw dataset — direct file links, a field dictionary, and a suggested citation format.
02
The data is deterministic, publicly observable technical evidence, not model-scored or AI-generated.
03
Reuse and cite freely; we ask that you link back to the source benchmark rather than republishing the raw numbers uncredited.
This page exists for one reason: to be the direct, stable link to the raw data — not another write-up of the findings.
If you're citing a specific figure, reanalyzing the sample, or building your own visualization, start here.
Download the data
domains-final.csv ↓
Domain-level evidence for all 100 companies: AI crawler access per bot, llms.txt state, schema presence, canonical and sitemap hygiene.
pages-final.csv ↓
Page-level evidence from the deterministic supporting-page sample beyond just the homepage.
benchmark-summary.json ↓
Machine-readable aggregate summary, including the four-category stratum breakdown.
Field dictionary (domains-final.csv)
company / stratumCompany name and its assigned category out of four stratified groups of 25.
robots_state / robots_http_statusWhether robots.txt was fetched successfully, and its HTTP status.
{bot}_statusOne column per tested crawler (oai_searchbot, gptbot, claudebot, perplexitybot, google_extended, and others) — allowed, blocked or unknown.
llms_txt_state / llms_txt_presentWhether /llms.txt exists, and whether it follows a structured format.
homepage_jsonld_presentWhether any application/ld+json markup was found in the initial homepage HTML.
homepage_organization_schema / _website_schema / _software_application_schemaPresence of each specific schema.org type on the homepage.
canonical_present / canonical_self_referencingWhether a canonical tag exists, and whether it points to the page itself.
sitemap_present / sitemap_url_countWhether a sitemap was found, and how many URLs it listed.
Full column definitions and collection notes are in the accompanying README published alongside the CSVs.
How to cite this dataset
Use freely, and please link back to the source benchmark rather than republishing figures without attribution:
Growthract. (2026). 2026 AI Search Readiness Benchmark: 100 B2B SaaS Websites [Dataset].
https://www.growthract.com/insights/blogs/ai-search-readiness-benchmark-2026
Cuts of this data we've already published
Before you rebuild an analysis from scratch, check whether we've already published it:
Limitations to carry into any reuse
This is a frozen, point-in-time sample of 100 companies, not a census of the B2B SaaS market. Unknown values were excluded from the relevant denominator rather than counted as failures — treat any percentage you compute the same way. Full methodology and limitations are documented in the main benchmark report.
Beyond the aggregate sample
Get the same signals checked for your own site.
Run Growthract's free diagnostic to check the same crawler access, llms.txt and schema signals against your own website.
FAQs
Can I republish charts built from this data?
Yes — please link back to this page or the main benchmark report as the source.
Will this dataset be updated?
It's currently a frozen snapshot from August 24, 2026. Any future refresh will be published as a dated update rather than silently overwriting these files.
What format are the files in?
Two are standard CSV files, and the summary is a machine-readable JSON file — all directly downloadable, no account or request required.
Continue exploring
Related insights
Case study
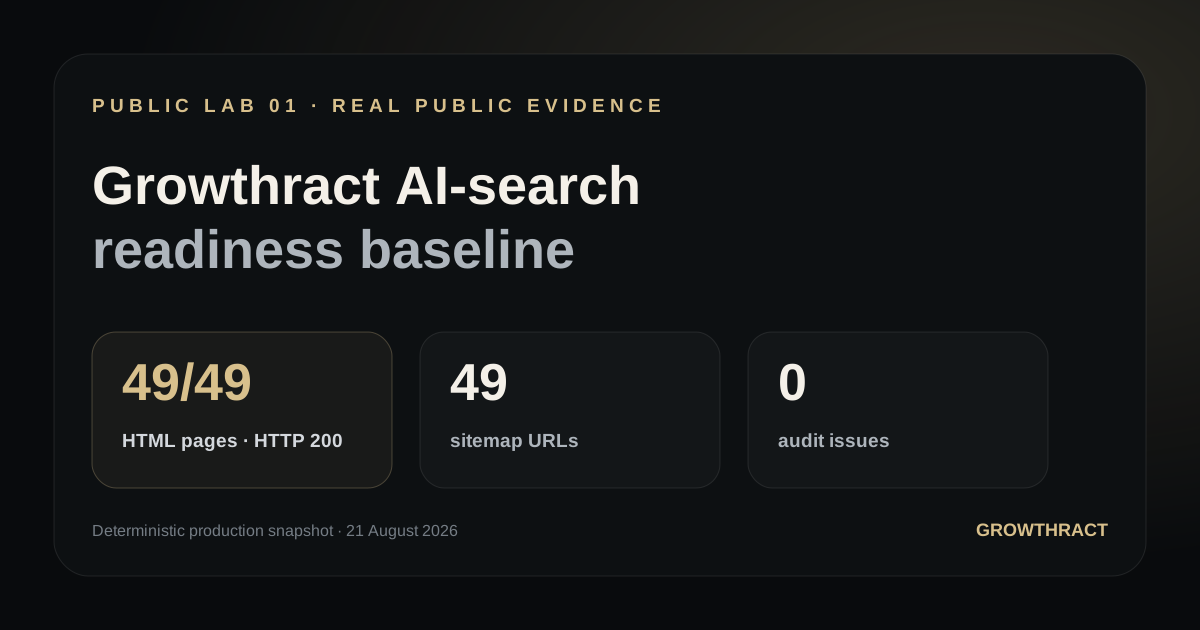
A public technical audit of growthract.com covering 49 production HTML pages, crawler access, robots.txt, sitemap integrity and legacy routes — with the limits of the evidence stated explicitly.
See the case study →
Insight
Original benchmark data comparing four B2B SaaS categories on llms.txt, schema and crawler-access signals — no single category wins on everything.
Read the insight →
Insight
Original research across 100 B2B SaaS websites on llms.txt adoption, AI crawler access, JSON-LD, schema markup, canonicals, and technical readiness.
Read the insight →